Neurobotics
Blended brain-machine control for human assistance using hybrid smart systems.
|
Funded by KU Leuven Internal Funds. |

Blended brain-machine control for human assistance using hybrid smart systems.
|
|
Funded by KU Leuven Internal Funds. |
Project Purpose: We study the use of computer vision and machine learning to assist paralyzed patients who interact with the world with a robot arm that they command via neural implants. We develop means of predicting the intent of the patient, from the onset of a purely patient-controlled motion, and a visual understanding of the workspace and objects that the user could potentially wish to interact with.
Shared Robot Control
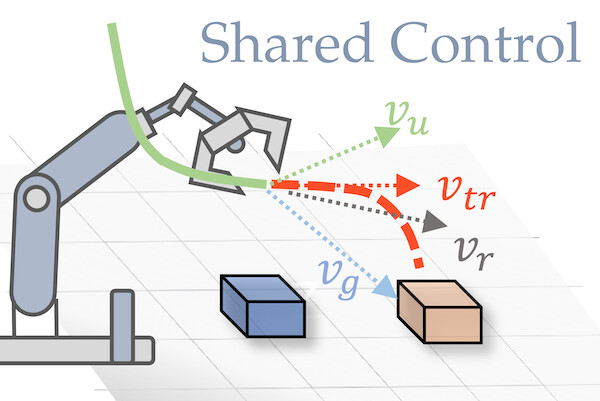
Our first publication [1] addresses the problem of (a) predicting the trajectory of an arm reaching motion, based on a few seconds of the motion’s onset, and (b) leveraging this predictor to facilitate shared-control manipulation tasks, by reducing the operator’s cognitive load through assistance in their anticipated direction of motion. Our novel intent estimator, dubbed the Robot Trajectron (RT), produces a probabilistic representation of the robot’s anticipated trajectory based on its recent position, velocity and acceleration history. By taking arm dynamics into account, RT can capture the operator’s intent better than other SOTA models that only use the arm’s position, making it particularly well-suited to assist in tasks where the operator’s intent is susceptible to change. We derive a novel shared-control solution that combines RT’s predictive capacity with a representation of the locations of potential reaching targets. Our experiments demonstrate RT’s effectiveness in both intent estimation and shared-control tasks. We have made the code and data supporting our experiments publicly available on our GitLab server.
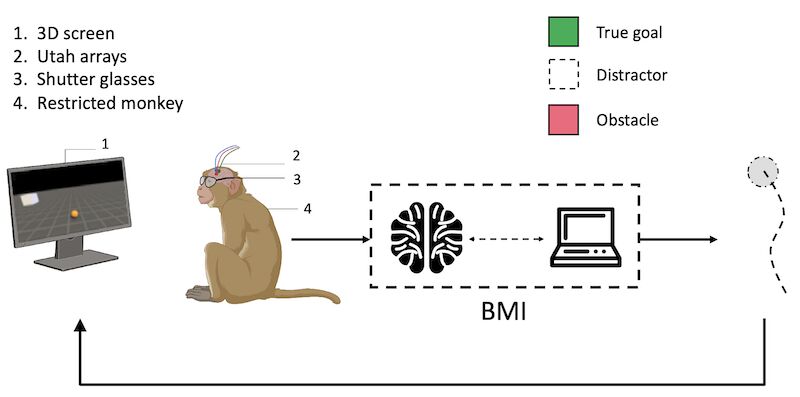
Robot Trajectron V2 (RT-V2) [2] brings this idea to navigation, in a probabilistic framework that combines a prior model of a user’s long-term behavior with a posterior update that accounts for their noisy, low-dimensional control signals. We validated RT-V2 across synthetic benchmarks, human–computer interaction studies with keyboard input, and brain–machine interface experiments with non-human primates. It outperforms the state of the art in intent estimation, while balancing user autonomy with assistive intervention. See the RT-V2 page.
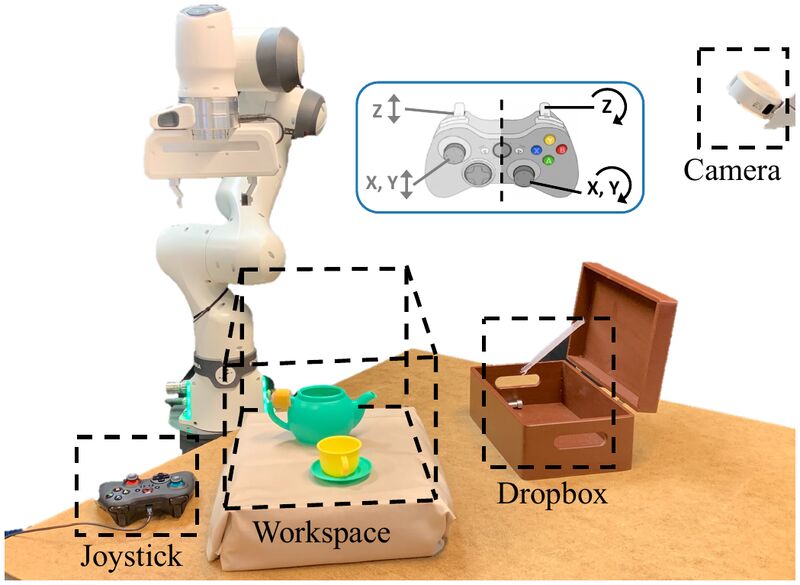
Robot Trajectron V3 (RT-V3) [3] extends this framework from navigation to SE(3) grasping, for high-DoF manipulation through low-bandwidth interfaces. The prior is a distribution over future trajectories, conditioned on past robot dynamics and on the scene, through a transformer-based generative model that reasons over point clouds and candidate grasp poses. During execution, RT-V3 continuously combines this prior with a likelihood derived from the user’s commands. In a real-world study with 21 novice participants using a joystick, RT-V3 reached a success rate of 86.9%, against 78.6% for direct teleoperation and 74.7% for Hindsight Optimization, and substantially reduced physical and mental workload. See the RT-V3 page.
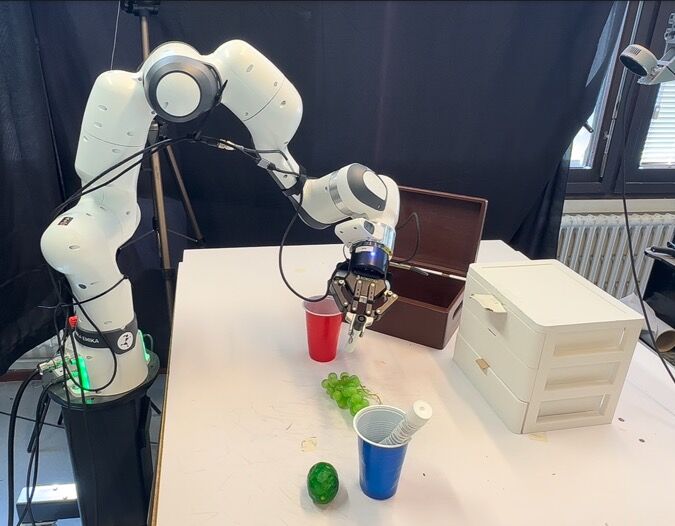
Assistron [4] explores a complementary route to assistance, by building on off-the-shelf Vision-Language-Action (VLA) models. Following the user’s verbal commands, the VLA autonomously executes reaching motions. When contact-rich interactions begin, where VLAs tend to fail, Assistron asks the user to intervene, and adjusts the VLA’s action generation through flow-matching guidance. This requires no fine-tuning of the VLA, which therefore keeps its broad behavioral priors. Assistron significantly improves task success over pure autonomy, and reduces workload compared to teleoperation. Our code is available. The study included able-bodied novice participants; evaluating Assistron with people with motor impairments is future work.
Scene Understanding
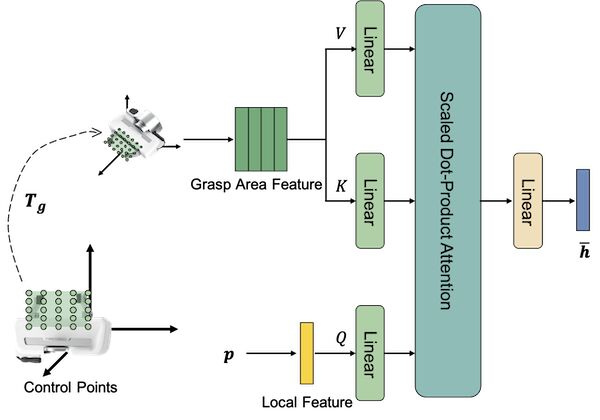
There are two dominant approaches in modern robot grasp planning: dense prediction and sampling-based methods. Dense prediction calculates viable grasps across the robot’s view but is limited to predicting one grasp per voxel. Sampling-based methods, on the other hand, encode multi-modal grasp distributions, allowing for different grasp approaches at a point. However, these methods rely on a global latent representation, which struggles to represent the entire field of view, resulting in coarse grasps. To address this, we introduce Implicit Grasp Diffusion (IGD) [5], which combines the strengths of both methods by using implicit neural representations to extract detailed local features and sampling grasps from diffusion models conditioned on these features. Evaluations on clutter removal tasks in both simulated and real-world environments show that IGD delivers high accuracy, noise resilience, and multi-modal grasp pose capabilities. Our code is freely available.
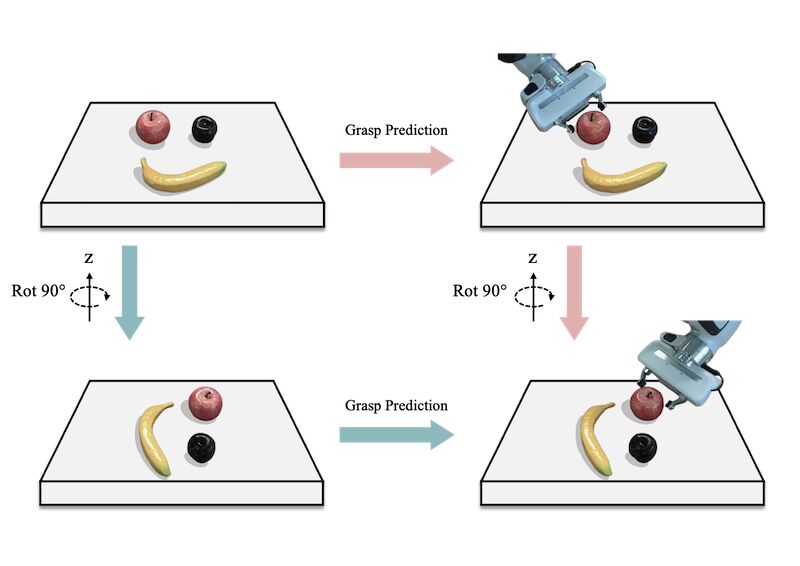
Equivariant Volumetric Grasping [6] is a volumetric grasp model that is equivariant to rotations around the vertical axis, which drastically improves sample efficiency. The model uses a tri-plane volumetric feature representation, i.e., the projection of 3D features onto the three XYZ canonical planes. We designed it such that features on the horizontal plane are equivariant to 90° rotations, while the sum of features from the other two planes remains invariant to the reflections induced by the same transformations. A key enabler is a new deformable steerable convolution, which combines the adaptability of deformable convolutions with the rotational equivariance of steerable ones. See the project page for code and videos.
 DOI
 Bib
 PDF
 Video
 arXiv
 Blog